After a handful of standalone posts on AI and security, I decided to organize everything in a public repository: a knowledge base, labs that actually run, and a framework any team can adopt.
Contents
- Introduction
- How it started
- The mental model
- Inside the repository
- The labs
- Key premises
- The framework
- The visual explorer
- Not ready yet
- Conclusion
- References
Introduction
Over the past few months I’ve written about AI, vibe coding and security, about how the stack behind these tools works and about why your AI agent needs a jail. Each post grew out of a different curiosity or annoyance, but always with the same maxim in mind: security.
In practice, what I ended up with was a pile of scattered notes, videos, links and tests that barely worked for me, let alone for anyone else.
So I decided to start turning all of that into something tangible. The first step is ai-security-playbook, a public GitHub repository with a visual explorer published on GitHub Pages so you can browse the content without cloning anything.
An important disclaimer, and one I make a point of repeating here: the repository content was produced and organized with the help of AI tools and is still being validated. It may contain errors, outdated information or incomplete guidance. Don’t treat anything in it as gospel; check the original sources (OWASP, ISO, vendor documentation) before applying it in production.
How it started
It would be hypocritical to write about AI security without making it clear that I used AI to organize the project. But as I’ve said in other posts, the output is only as good as what you put in, so the part I most want to share is how I ran the process and how it can be useful.
I started with an initial prompt describing my needs and the outcome I expected, defining:
- Role: AI security engineer and open source maintainer.
- Goal: for the repository to serve as (a) an organized knowledge base, (b) a lab for reproducible experiments and (c) a shareable framework.
- Topics: secure system prompts, skill and agent scanning, agent sandboxing, prompt anonymization, strategies against prompt injection, auditing without bringing productivity to a halt, OWASP LLM Top 10, ISO/IEC 42001 and a consolidated framework.
- Working rules, also an important part of the prompt.
The work was split into phases (scaffolding, knowledge base, labs, consolidated framework and publishing), each one ending with a summary of what was done and what was still pending verification. It’s essentially the same Spec Driven Development principle I discussed in part 1: specify first, execute second, review at every step.
The mental model
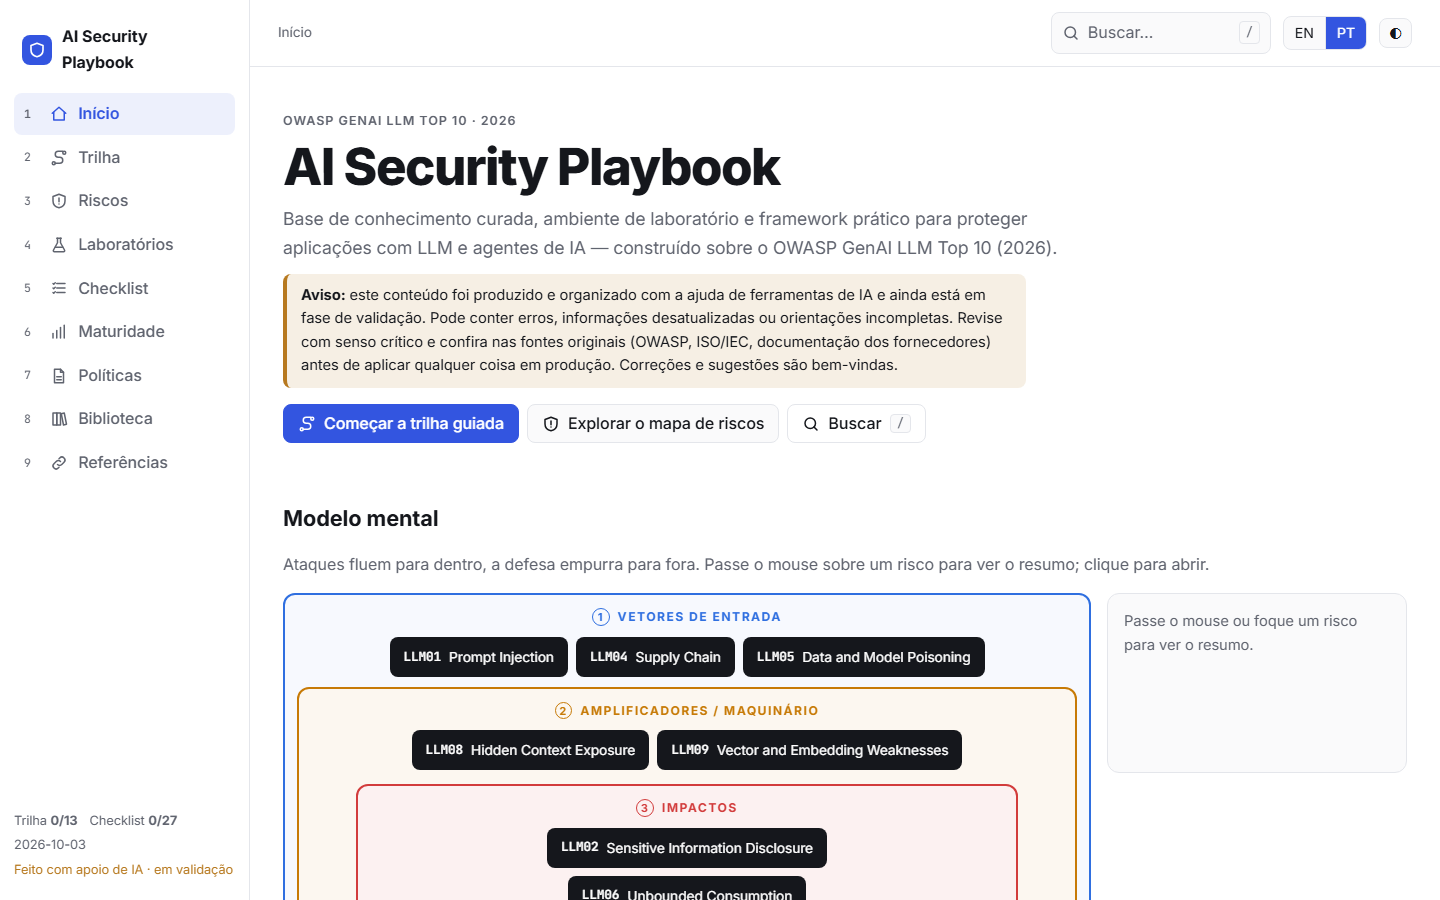
I’ve always trusted the quality of OWASP’s frameworks, so I wanted the foundation to be the OWASP GenAI LLM Top 10 (2026), plus a diagram that organizes the risks in layers: attacks flow inward, defense pushes outward. That makes the big picture easy to see and lets you move dynamically between the layers.
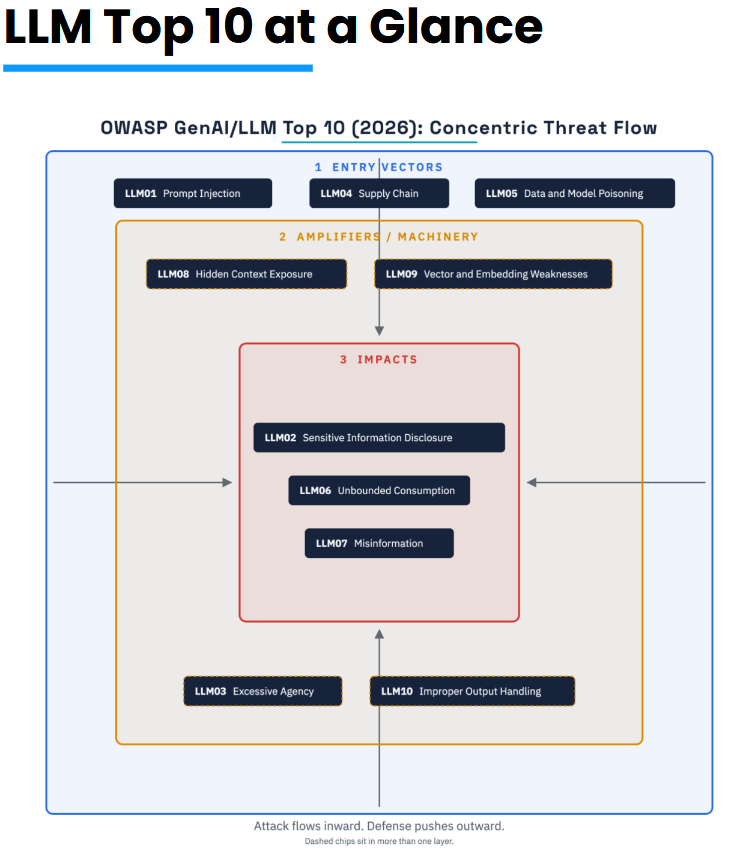
- Entry vectors (where the attacker gets in): LLM01 Prompt Injection, LLM04 Supply Chain and LLM05 Data and Model Poisoning.
- Amplifiers / machinery (what makes an entry point dangerous at scale): LLM08 Hidden Context Exposure and LLM09 Vector and Embedding Weaknesses.
- Impacts (what actually goes wrong): LLM02 Sensitive Information Disclosure, LLM06 Unbounded Consumption and LLM07 Misinformation.
- Boundary risks (can show up at any layer): LLM03 Excessive Agency and LLM10 Improper Output Handling.
Inside the repository
| Folder | What it’s for |
|---|---|
docs/owasp-llm/ |
One page per Top 10 risk: description, attack scenarios, mitigations, tests and links |
docs/strategies/ |
Prompt injection and the gradual adoption model (audit without blocking) |
docs/iso-42001/ |
Mapping between ISO/IEC 42001 and the repository’s practices |
docs/framework/ |
Checklist, maturity model and templates |
system-prompts/ |
Annotated base system prompts, with rationale and limitations |
labs/ |
Four reproducible labs |
policies/ |
Sample allowlists, spending limits, hooks and an escalation matrix |
resources/links.md |
Curated links, with access date and maintenance status |
site/ |
The visual explorer published on GitHub Pages |
The labs
AI Jail, the sequel to my previous post
In the post about the jail, I argued for isolating the agent at the operating system level with bubblewrap. The playbook’s lab shows another side of the same problem, in two layers:
- A tool gateway in the application: every call is validated by name and by argument, denied by default and logged. Authorization happens in code, outside the model, not by politely asking in the system prompt.
- A container underneath, with no root, no network and a read-only filesystem. If the gateway fails (a bug, a compromised dependency), the damage stays contained.
One layer doesn’t replace the other. Same idea as always: the more layers, the smaller the blast radius.
demo_agent.py simulates six calls: two legitimate ones and four that mimic what a successful prompt injection would attempt (path traversal, a read by absolute path, a tool that was never registered, a giant write). The expected result is that the first two go through and the last four are denied, with the reason logged.
SkillSpector, skill scanning
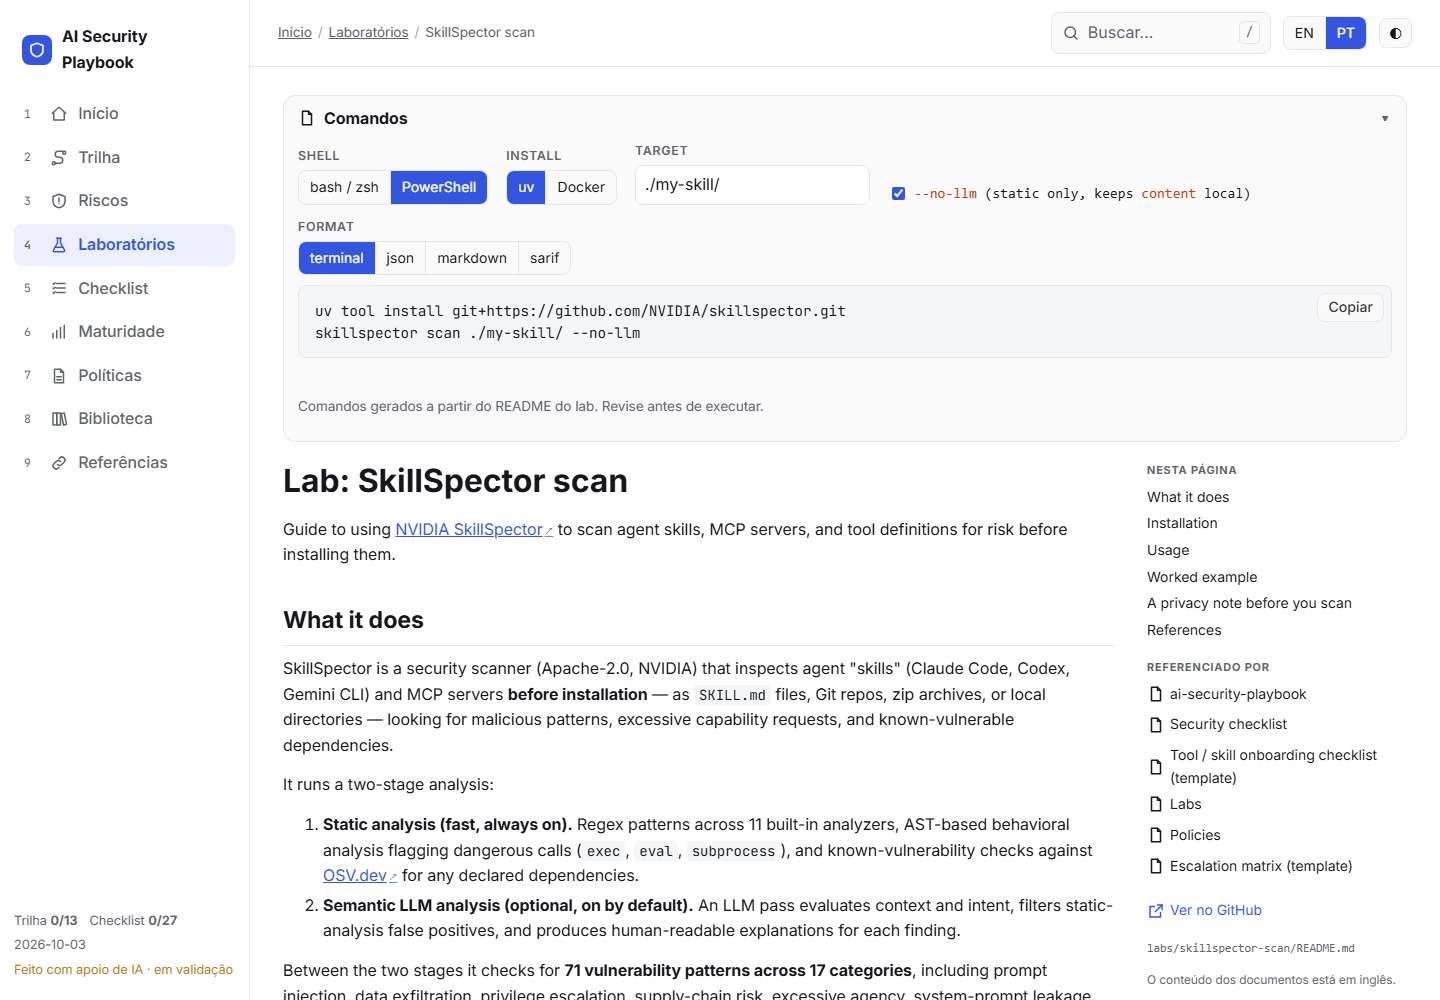
Skills and MCP servers have become the “npm install” of the agent world: we install third-party stuff that then gets access to our machines. NVIDIA’s SkillSpector analyzes skills and MCP servers before installation, using static analysis and, optionally, LLM-based semantic analysis, and returns a risk score from 0 to 100.
The repository’s guide covers installation, examples and one point I think is easy to forget: the semantic step sends the scanned content to the configured LLM provider. If what you’re scanning might contain anything sensitive, start with --no-llm. The takeaway: even a security tool has to be evaluated for data leakage.
Prompt anonymization
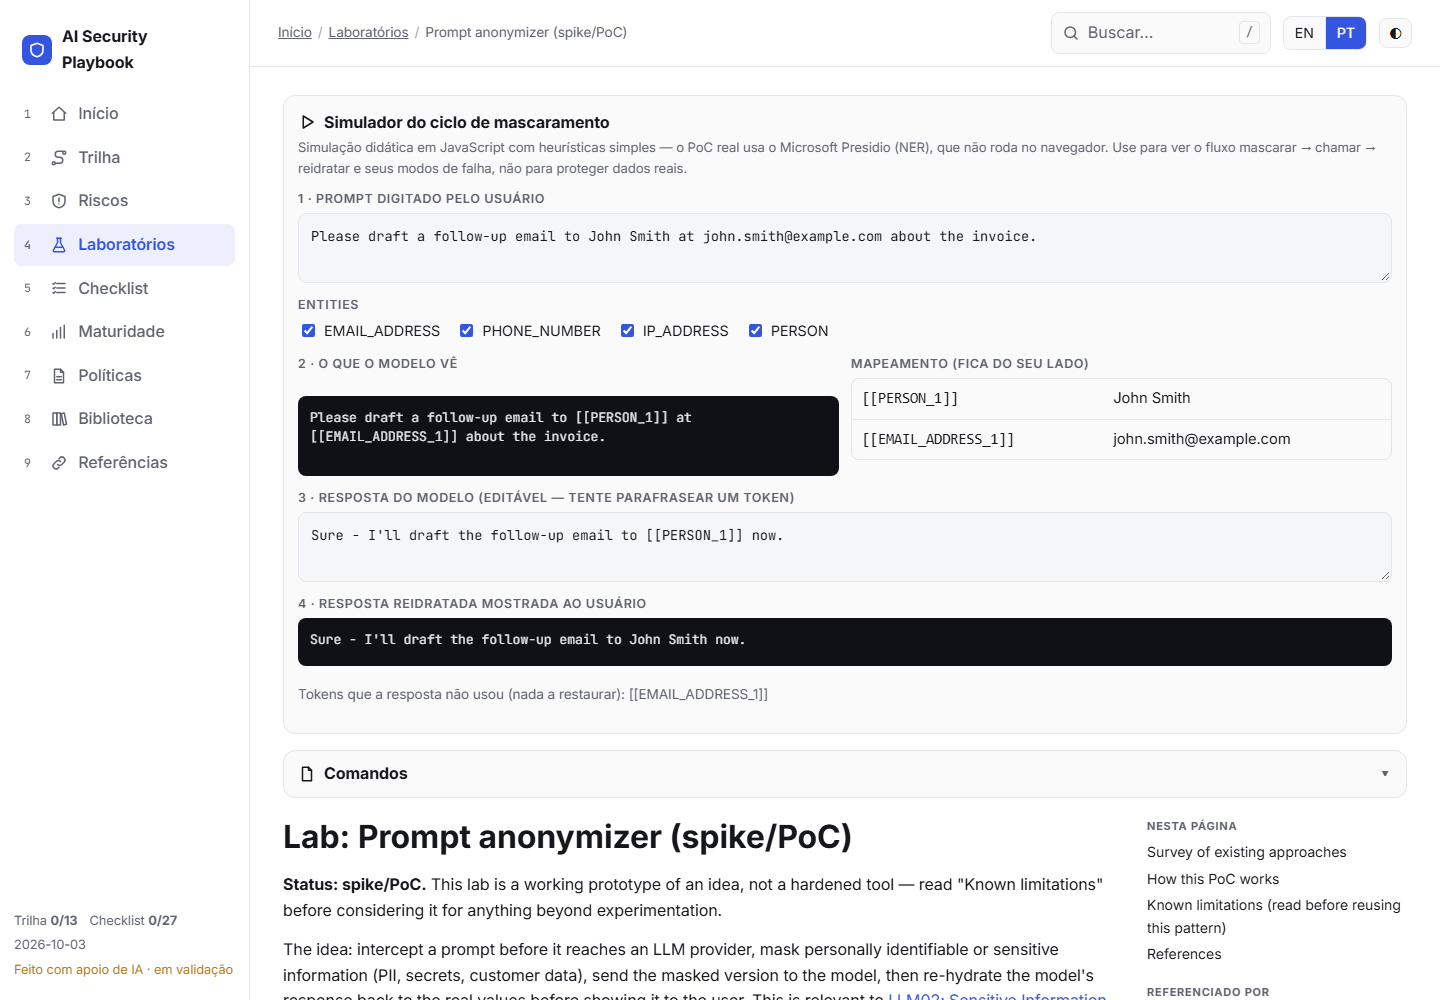
This is the most experimental idea, and it’s openly labeled as a spike/PoC. The reasoning goes like this: intercept the prompt, mask sensitive data (personal data, secrets, customer data), send the masked version to the model and, on the way back, “rehydrate” the response with the real values.
Before implementing anything, the repository compares the existing approaches. The prototype uses Microsoft Presidio, which is actively maintained and was the most mature open source option I found in my research. One finding caught my attention: llm-guard, which would be an obvious candidate, shows up as archived in July 2026, which takes it off the list for new projects.
The lab’s README is quite candid about the limitations, and I think they’re the most valuable part:
- Rehydration only works if the model returns the placeholder exactly as it received it. Models paraphrase, translate and reformat.
- Detection is probabilistic. “Presidio didn’t flag it” doesn’t mean “there’s nothing sensitive.”
- Masking the string doesn’t prevent inference from context.
- None of this replaces reading your provider’s retention and training policy.
Injection tests
An educational set of prompt injection cases across three surfaces: direct, indirect (retrieved content, RAG, documents) and tool-based (agents, MCP). Every case was written from scratch for the repository, based on publicly known techniques, and comes with the expected safe behavior and the corresponding mitigation.
The runner is deliberately simple: it does a rough keyword check and flags REVIEW. It’s a triage aid, not a verdict. For serious work, the repository points to tools such as promptfoo, garak and PyRIT.
Key premises
1. Prompt injection has no definitive fix.
Language models process instructions and data in the same token stream, and there’s no equivalent of a parameterized query. OWASP and NIST are explicit that there is currently no reliable prevention mechanism, and any solution that promises to “solve” the problem deserves suspicion.
The strategy is to reduce the blast radius, and two mental models are documented for that:
- Agents Rule of Two (Meta): an agent session should not, at the same time, process untrusted content, access sensitive systems or data and take high-impact actions autonomously. If the workflow needs all three, require human approval for each action.
- Lethal trifecta (Simon Willison): private data + untrusted content + an external communication channel. That combination turns injection into exfiltration.
This ties back to what I wrote in the ai-jail post: once you accept that the agent will read content you don’t control, the question becomes what it can do when that goes wrong.
2. Audit without blocking
Most AI security controls fail at adoption, and not because they’re technically wrong. They get switched on as a hard block on day one, break a legitimate workflow and get turned off by the first frustrated team. Anyone who works in corporate information security and compliance has seen this movie before.
The proposal is a gradual adoption model:
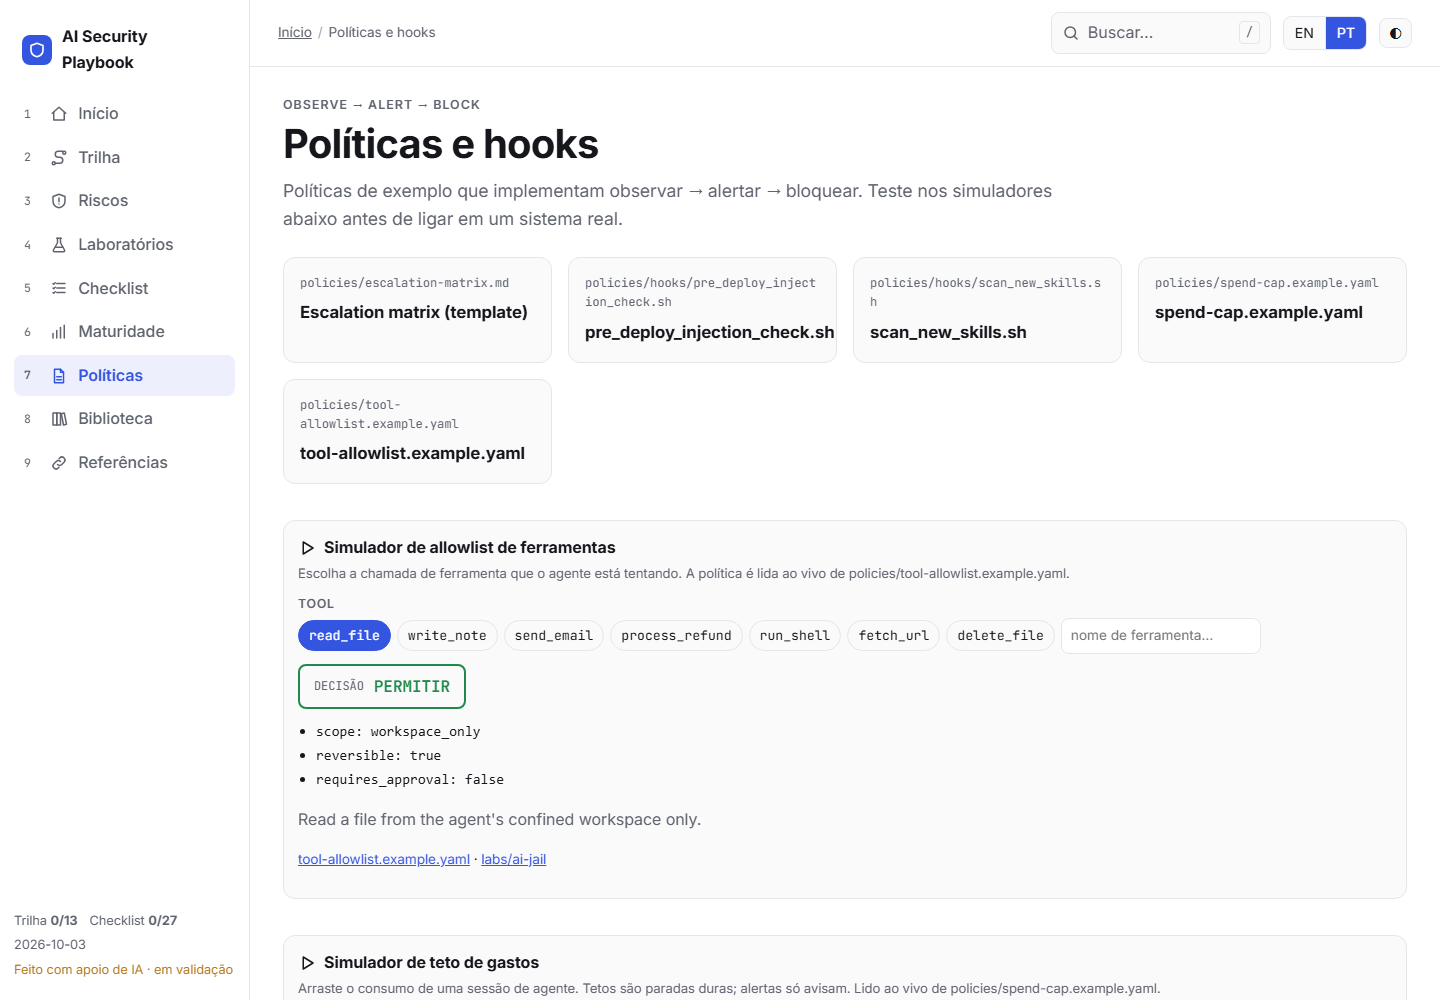
- Observe: log the event and do nothing else. The question is “if this had been blocking today, what would have broken?”
- Alert: notify a human without blocking, while tuning out false positives.
- Block, with graduated enforcement: actions that are cheap to undo are auto-approved, while irreversible or high-impact actions (an external payment, a write to a production database, a permission change) require human approval or a hard block.
Keep in mind that logs and traces can contain sensitive data too, so they deserve access control.
The framework
All of this comes together in three pieces you can copy and use:
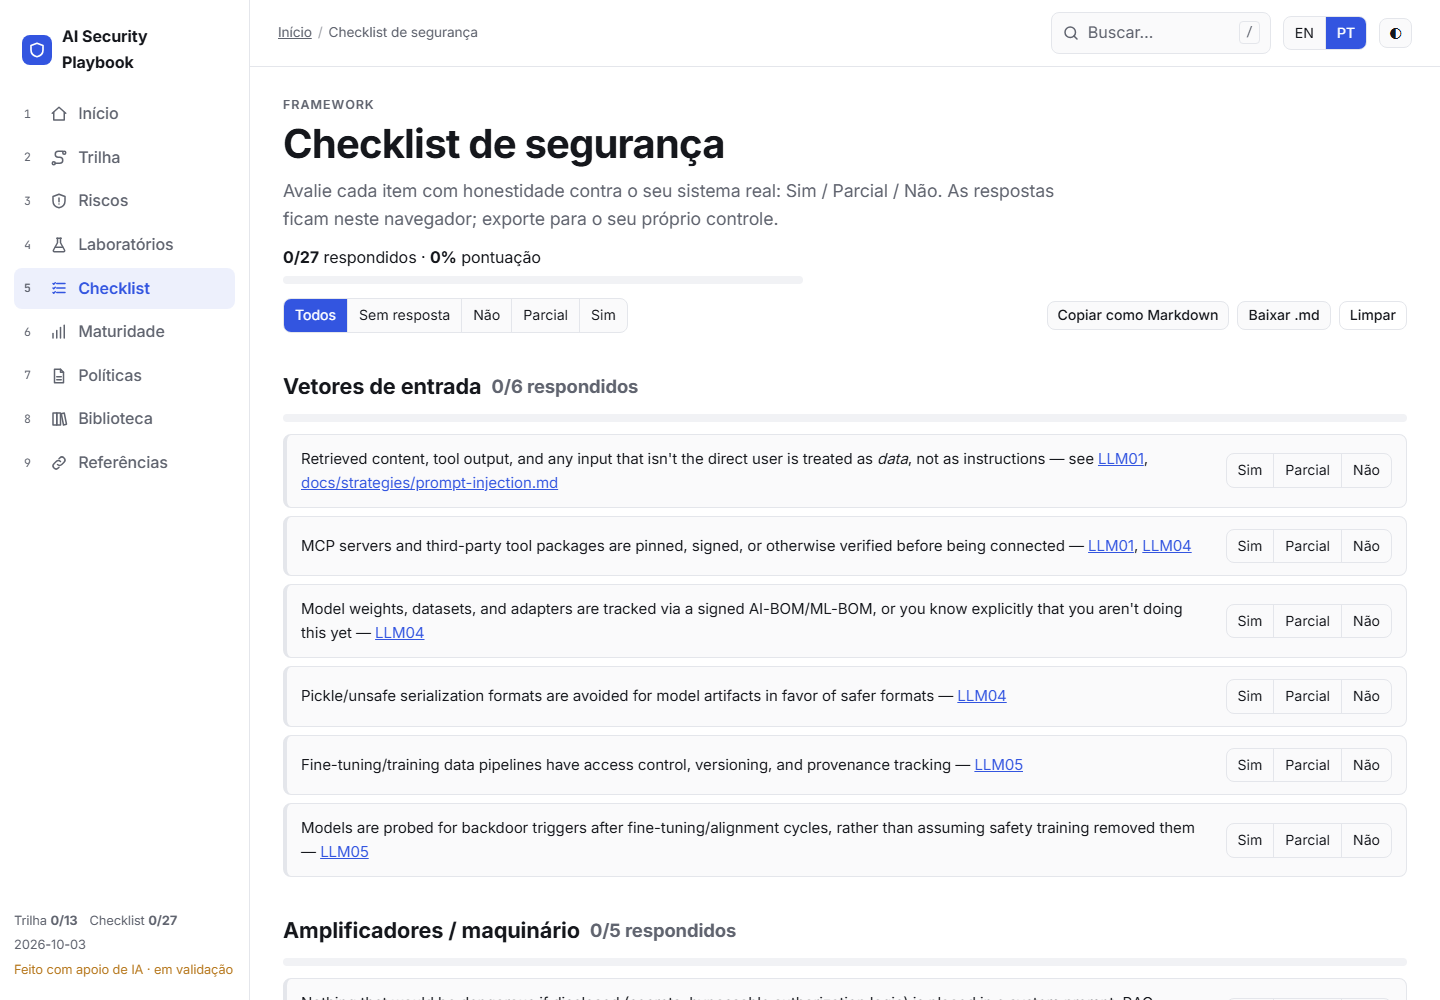
- Checklist organized by the layers of the OWASP LLM Top 10, with each item pointing to its source OWASP risk. The guidance is to answer Yes / Partial / No honestly, with the goal of measuring your maturity level.
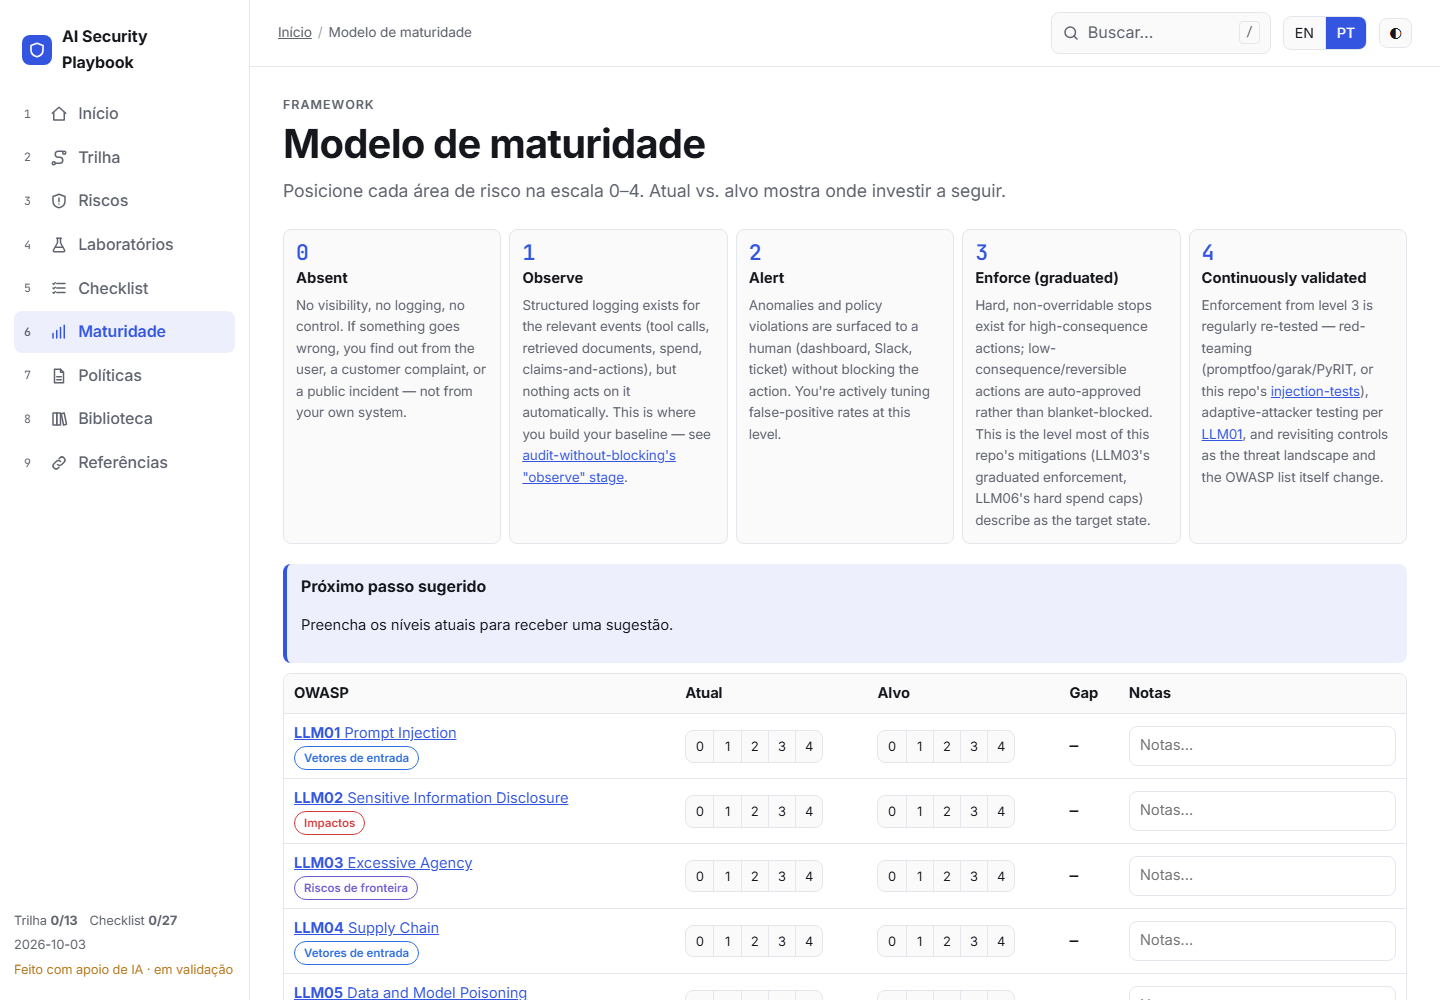
- Maturity model with 5 levels, applied per risk rather than as a single score for the whole system: Absent → Observe → Alert → Enforce → Continuously validated. Levels 1 to 3 follow the gradual adoption model, and level 4 exists because controls that are correct today silently rot when attack techniques (or the OWASP list itself) change.
- Templates for recurring reviews: pre-launch risk review, tool/skill onboarding and incident log.
There’s also a mapping to ISO/IEC 42001. I need to be clear about this, just as the repository itself is: it’s a reference mapping, not a claim of compliance. Selecting and justifying Annex A controls depends on the organization’s own risk and impact assessment, and that’s beyond the scope of this project.
The visual explorer
Since browsing dozens of Markdown files on GitHub isn’t the most pleasant experience, I built a static site that reads the repository’s own content (without duplicating anything) and offers a guided path, a risk map, an interactive checklist, a maturity board, search and simulators for the sample policies.
I also wanted some of the labs to run right in the browser. The tool gateway and the injection test runner run on Python compiled to WebAssembly (Pyodide), and you can edit the files before each run. Nothing is sent anywhere: checklist answers live only in your browser’s localStorage, and there’s no backend or analytics. Third-party libraries are pinned to fixed versions with recorded hashes, and the rendered Markdown is sanitized.
The anonymizer depends on Presidio and spaCy models and doesn’t run in the browser, so there’s a teaching simulator in JavaScript instead. It’s useful for understanding the flow and its failure points, but it should never be used to protect real data.
Not ready yet
- The system prompts and hooks are documented and tested internally, but they haven’t been red-teamed against a real production system yet. Don’t treat them as validated security boundaries.
- The
[to verify]markers scattered throughout the docs mean exactly that: something I couldn’t confirm and that was left visible instead of being silently resolved. - The OWASP LLM Top 10 is revised periodically. The repository tracks the 2026 edition and will need to be rechecked against future ones.
- All of this was put together with AI and went through my review, but I haven’t yet independently audited and run every instruction.
Conclusion
There’s no shortage of repositories listing tools and frameworks, but I wanted to put together a kind of “curated selection” of what to actually implement, without getting overwhelmed and lost in the thousands of options out there.
The project is open source (MIT license) and contributions are very welcome: issues and PRs pointing out anything outdated, wrong or uncited help make it better. Take a look, break whatever you think deserves breaking, and pitch in.
- Repository: github.com/Gadotti/ai-security-playbook
- Explorer: gadotti.github.io/ai-security-playbook
References
My project and related posts
- ai-security-playbook, GitHub repository
- ai-security-playbook, explorer on GitHub Pages
- OWASP numbering verification note
- AI everywhere: Theories, lessons and vibe coding
- AI everywhere: Theories, lessons and vibe coding - Pt. 2
- Why your AI agent needs a “jail”